Any web page to clean Markdown and metadata
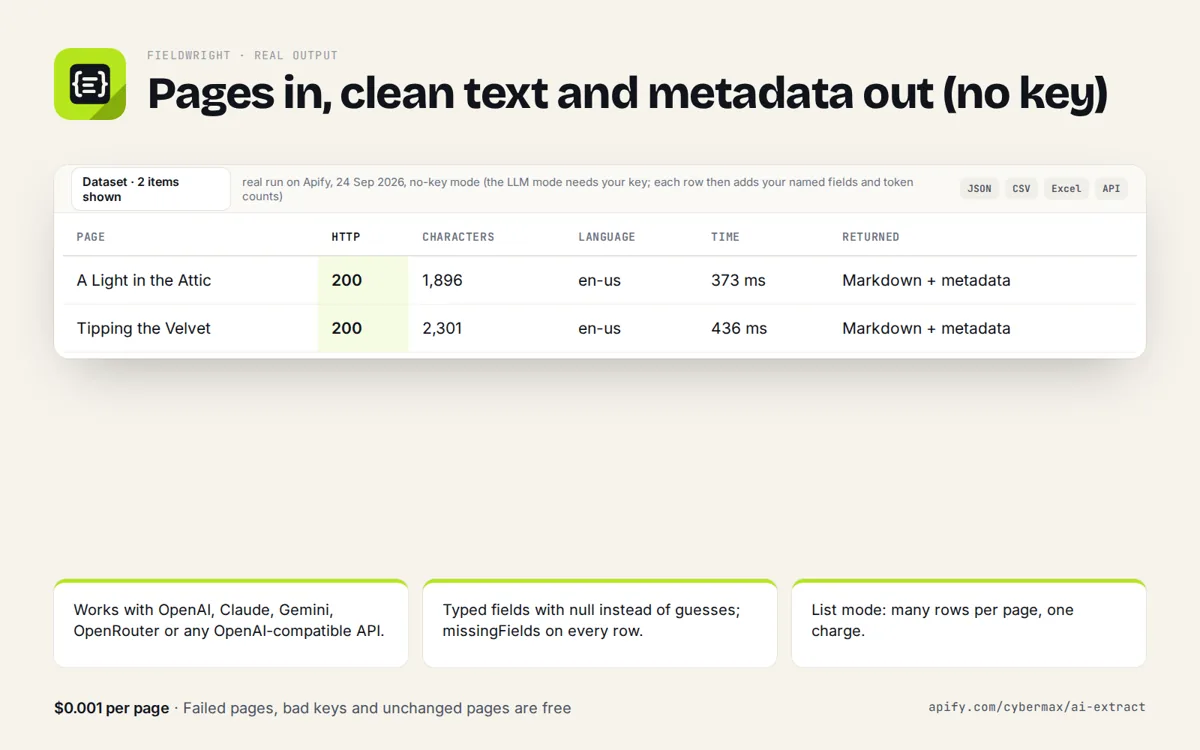
Give a URL, get the page as compact Markdown (links and tables kept) plus its title, description, language, canonical URL, OpenGraph tags, JSON-LD structured data, emails and phone numbers. No AI key needed.
Opens Stripe's billing portal: invoices, payment method, cancel.
Who it's for
Anyone who needs this answer fast, from a person to an AI agent.
Feed a model the readable text of a page, not 300 KB of HTML.
Check a page's title, description, canonical, OpenGraph and schema.org markup.
Get JSON-LD (products, articles, events, organisations) from a URL in one call.
Save pages as Markdown with their links and tables intact.
Try it
Paste any public page URL. You get its metadata and readable Markdown.
Raw JSON response
Real sample output
Captured from a live call to this API (trimmed for length).
{
"results": [
{
"url": "https://books.toscrape.com/catalogue/a-light-in-the-attic_1000/index.html",
"finalUrl": "https://books.toscrape.com/catalogue/a-light-in-the-attic_1000/index.html",
"title": "A Light in the Attic | Books to Scrape - Sandbox",
"pageChars": 1877,
"truncated": false,
"httpStatus": 200,
"fetchedVia": "direct",
"ok": true,
"mode": "no-llm",
"description": "It's hard to imagine a world without A Light in the Attic. This now-classic collection of poetry and drawings from Shel Silverstein celebrates its 20th anniversary with this special edition. Silverstein's humorous and creative verse can amuse the dowdiest of readers. Lemon-faced adults and fidgety kids sit still and read these rhythmic words and laugh and smile and love th It's hard to imagine a world without A Light in the Attic. This now-classic collection of poetry and drawings from Shel Silverstein celebrates its 20th anniversary with this special edition. Silverstein's humorous and creative verse can amuse the dowdiest of readers. Lemon-faced adults and fidgety kids sit still and read these rhythmic words and laugh and smile and love that Silverstein. Need proof of his genius? RockabyeRockabye baby, in the treetopDon't you know a treetopIs no safe place to rock?And who put you up there,And your cradle, too?Baby, I think someone down here'sGot it in for you. Shel, you never sounded so good. ...more",
"language": "en-us",
"canonicalUrl": null,
"openGraph": {},
"jsonLd": [],
"emails": [],
"phones": [],
"markdown": "[Books to Scrape](https://books.toscrape.com/index.html) We love being scraped!\n\n- [Home](https://books.toscrape.com/index.html)\n- [Books](https://books.toscrape.com/catalogue/category/books_1/index.html)\n- [Poetry](https://books.toscrape.com/catalogue/category/books/poetry_23/index.html)\n- A Light in the Attic\n\n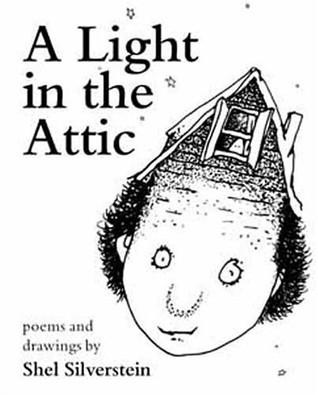\n\n# A Light in the Attic\n\n£51.77\n\nIn stock (22 available)\n\nWarning! This is a demo website for web scraping purposes. Prices and ratings here were randomly assigned and have no rea…",
"ms": 176,
"extractedAt": "2026-09-25T23:03:28.294Z"
}
],
"count": 1
}Limits, plainly
Free and rate limited so it stays fast for everyone. A bulk and scheduled version for big lists is coming to the Apify Store.
- 20 calls per minute per IP address.
- One URL per call.
- Markdown up to 20,000 characters (default 8,000); pages up to 1 MB.
- About 15 seconds per call at most. No JavaScript rendering.
- Free, no key. No AI model runs here and no keys are accepted.
Get an API key
URL to clean Markdown for LLMs and RAG: one call returns the page as compact Markdown (links and tables kept) plus title, description, language, canonical URL, OpenGraph, JSON-LD, emails and phone numbers. No AI key needed. Keys work on the REST API and the MCP server.
14-day money-back promise: if it doesn't work as described, email us within 14 days and we fix it or refund you in full. Refund terms.
25,000 pages a month · 120 per minute
Get Builder keyor $490/year, 2 months freePay with card, Apple Pay, Google Pay or Link through Stripe Checkout (sales tax/VAT handled by Stripe). Your key appears on the page you return to right after checkout: save it. Manage or cancel any time at fieldwright.cybermax-tools.workers.dev/manage. Send it as x-api-key: YOUR_KEY (or Authorization: Bearer YOUR_KEY, which MCP clients support). Check usage at /key. Failed calls are not counted. URL-to-Markdown APIs charge per page: Firecrawl Hobby $19 for 5,000 ($16 billed yearly), Diffbot $299 for 250,000, Apify $0.20 to $5 per 1,000 on compute (checked 27 Sep 2026). Fieldwright Reader is $19/month for 7,500 pages (50% more than Firecrawl Hobby), Scale $99 for 100,000, or $5 pay-as-you-go for 1,500 pages.
Using several CyberMax APIs? CyberMax API All-Access: one key for all 10 APIs (this one included, 7,500 pages a month here) for $119/month. See All-Access
curl -s "https://fieldwright.cybermax-tools.workers.dev/api/extract?..." -H "x-api-key: YOUR_KEY"

# MCP (Claude Desktop, Cursor, VS Code)
{ "mcpServers": { "fieldwright": { "type": "http", "url": "https://fieldwright.cybermax-tools.workers.dev/mcp",
  "headers": { "Authorization": "Bearer YOUR_KEY" } } } }

# Usage so far
curl -s https://fieldwright.cybermax-tools.workers.dev/key -H "x-api-key: YOUR_KEY"
Use the API
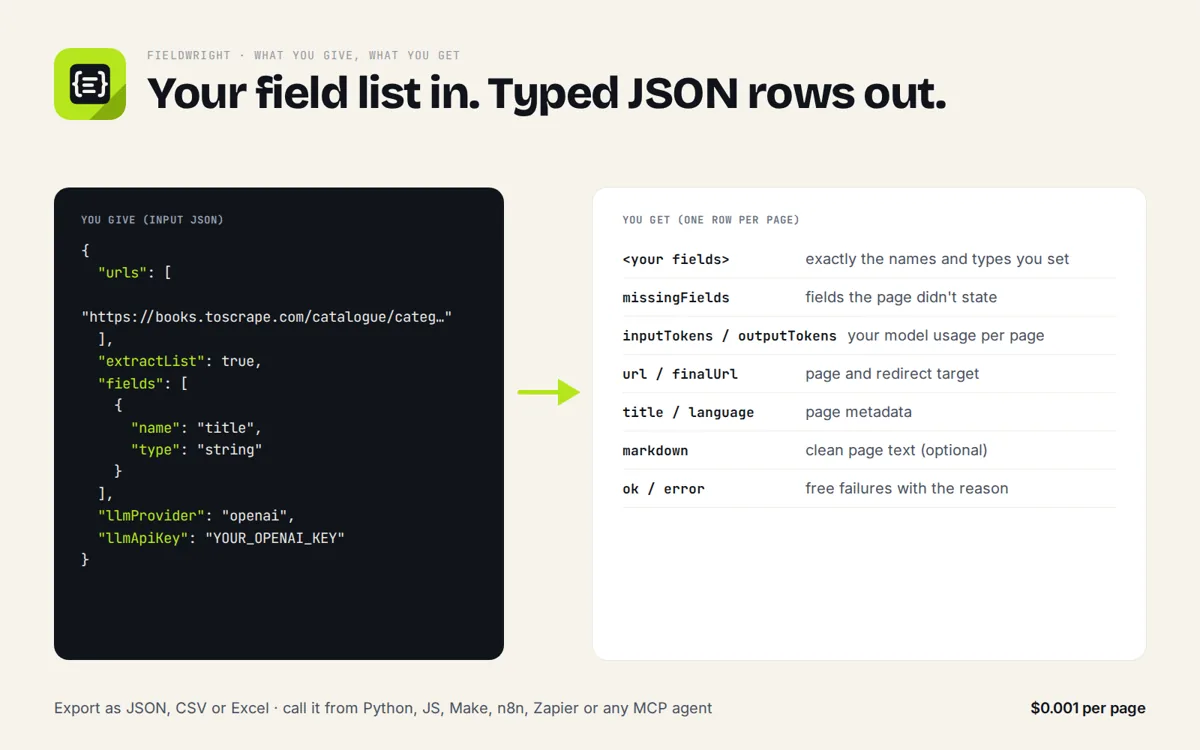
JSON over HTTPS, CORS enabled, no key. GET for quick calls, POST a JSON body for lists. Spec: openapi.json · llms.txt
curl -s "https://fieldwright.cybermax-tools.workers.dev/api/extract?url=https%3A%2F%2Fbooks.toscrape.com%2Fcatalogue%2Fa-light-in-the-attic_1000%2Findex.html&maxChars=4000"

# lists: POST a JSON body
curl -s -X POST https://fieldwright.cybermax-tools.workers.dev/api/extract \
  -H "content-type: application/json" \
-d '{"url":"https://books.toscrape.com/catalogue/a-light-in-the-attic_1000/index.html","maxChars":4000}'import requests
r = requests.post("https://fieldwright.cybermax-tools.workers.dev/api/extract",
json={"url":"https://books.toscrape.com/catalogue/a-light-in-the-attic_1000/index.html","maxChars":4000}, timeout=30)
r.raise_for_status()
for row in r.json()["results"]:
print(row)Endpoints: /api/extract one url to markdown + metadata (no-key mode)
Add it to your AI agent (MCP)
A remote MCP server at https://fieldwright.cybermax-tools.workers.dev/mcp (streamable HTTP, no auth). Read-only tools with JSON schemas, so agents know exactly what to send.
// Claude Desktop, Cursor, VS Code, any MCP client (remote, no key)
{
  "mcpServers": {
    "fieldwright": { "type": "http", "url": "https://fieldwright.cybermax-tools.workers.dev/mcp" }
  }
}

# Claude Code
claude mcp add --transport http fieldwright https://fieldwright.cybermax-tools.workers.dev/mcp

# Tools: extract_page
# e.g. extract_page({"url":"https://books.toscrape.com/","max_chars":3000})
extract_page
Fetch one public web page and return its readable content as compact Markdown (links and tables kept) plus title, meta description, language, canonical URL, OpenGraph/Twitter tags, JSON-LD structured data (products, articles, organisations, events), mailto emails and tel phone numbers. Use to read or summarise a page or pull its schema.org data. No JavaScript rendering.
FAQ
Why not an LLM scraper?
For reading a page you often don't need a model at all: Fieldwright returns the page's own structured data (JSON-LD, OpenGraph) and clean Markdown in about a second, for free, with the same output every time. Hand the Markdown to your own model if you need more.
Does it run JavaScript?
No. It reads the HTML the server sends. Pages that only render with JavaScript come back with little text.
Do I need an API key or an OpenAI key?
No. This free API runs in no-key mode only and refuses any LLM key you send. Typed extraction with your own model is part of the bulk version coming to the Apify Store.
Which pages can I fetch?
Public pages you are allowed to access. Respect each site's terms; login-only content is not supported.
Can I process many URLs?
The free API takes one URL per call (20 calls a minute). A bulk and scheduled version is coming to the Apify Store.